Image generation
image_generate lets a run draw a picture with an image model on your own
machine. Ask for one in any conversation — "make me a poster for Friday's lab
meeting that says 'Journal Club'" — and the model describes it as a scene,
the tool writes the image model's prompt from that, the image server renders
it, and the PNG is saved under images/ in the conversation's workspace. Web
chat shows it under the call; the terminal shows the path.
It is registered only when [image] is configured. With none, the tool does
not exist.
Setting it up
mecha does not run the image model itself; it talks to a local server. Today that server is ComfyUI running Qwen-Image 2.1, with the diffusion model as the int8 file from Comfy-Org/Qwen-Image-2.1 (the bf16 file on a Mac, below).
On Linux with an NVIDIA driver 580 or newer, mecha features enable image
installs it: ComfyUI at a pinned commit, torch for CUDA 13 from a
hash-pinned lock (about 3.6 GiB), the three model files by their pinned
sha256 (about 14 GB) under ~/.mecha/sidecars/comfyui/, and two user units:
mecha-comfyui.service on :8188, and mecha-comfyui-idle.timer, which
gives the server's memory back when it sits unused (below). The install
checks that the server has every
node and model mecha's pictures use, and writes an [image] table naming the
server's temp directory if your config has none. A ComfyUI you already run on
:8188 is left alone and used.
On a Mac with Apple silicon, the same command installs it too, drawing on
the GPU through MPS: ComfyUI at the same commit, PyPI's torch from its own
hash-pinned lock (about 0.76 GB), and the bf16 model files (about 21 GB) —
Apple's GPU has no int8 kernels, so the int8 file is emulated there and
slower (about 128 s a picture against 79 s for bf16 on an M5 Max). The server
is a launchd agent, ai.mecha-factory.mecha-comfyui, logging to
~/Library/Logs/mecha/mecha-comfyui.log. On a Mac ComfyUI runs on demand:
the agent holds port 8188, starts ComfyUI at the first picture (a cold start
adds about 20 s) and stops it after fifteen idle minutes, giving all of its
memory back. The text encoder runs on the CPU there, which adds about 13 s to a
new prompt. It needs macOS 14 or newer; an Intel Mac is not offered the
install.
To run your own instead:
- Put the three model files where ComfyUI looks for them — the diffusion
model under
models/diffusion_models/, the text encoder undermodels/text_encoders/, the VAE undermodels/vae/. - Run ComfyUI on this machine only:
python main.py --listen 127.0.0.1 --port 8188. - Add the section to
~/.mecha/config.toml(the global file — a project'smecha.tomlcannot configure this):
[image]
url = "http://127.0.0.1:8188"
diffusion_model = "qwen_image_2.1_int8_convrot.safetensors"   # qwen_image_2.1_bf16.safetensors on a Mac
text_encoder = "qwen3vl_8b_w4a8.safetensors"
vae = "qwen_image_2.1_vae_bf16.safetensors"
mecha tools lists image_generate once it is configured. Every key and its
default is in the configuration reference.
A .gguf diffusion model works too, through the
ComfyUI-GGUF node: name the file
and mecha uses that node for it. On the DGX Spark the int8 file is more than
twice as fast — about 28 seconds a picture against 64 for the Q4 GGUF, and 37
against about 80 for an edit — with the same pictures for the same seed and
about 1 GB more memory at its peak.
Settings → Images sets how pictures are drawn in chat: the model,
steps, guidance, sampler, scheduler and whether the fixed negative prompt is
sent, with presets for the reference setting, a guided one and turbo. A
persona's page has the same settings, and each one it leaves at "chat"
follows Settings → Images, so you tune once and override per persona. A
persona that picks a different model from the chat's takes that model's own
numbers rather than the chat's. The settings are kept in
~/.mecha/picture-settings.toml and a persona's state.toml, written only
by those pages, and read on every picture, so a change is the next
picture's.
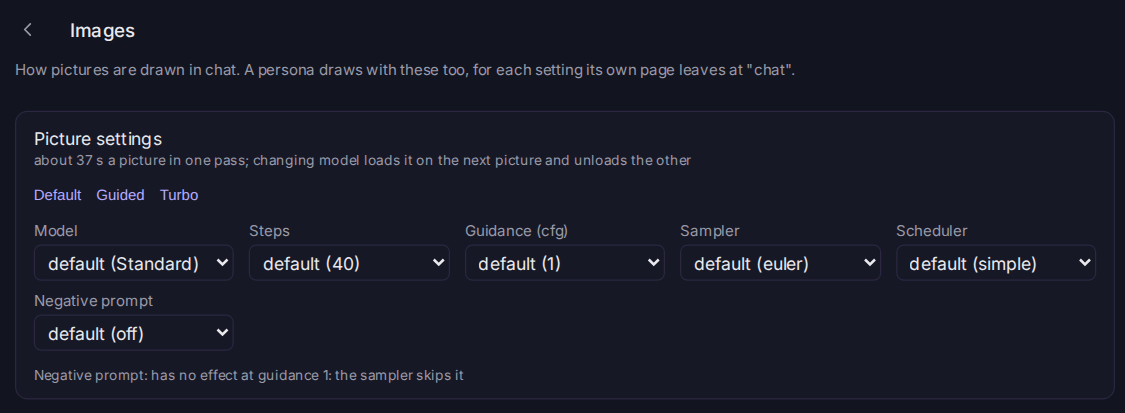
Either page can switch pictures to the turbo model. It draws in
about 8 steps instead of 40, so a picture takes 10 to 15 seconds, but it is
weaker on two people acting together. Turbo needs one more file from the
same repository, qwen_image_2.1_turbo_int8_convrot.safetensors (the
qwen_image_2.1_turbo_bf16.safetensors on a Mac), also under
models/diffusion_models/ ([image] turbo_model names it). The install does
not fetch it unless asked: mecha features enable image --turbo does, and so
does mecha features enable image once the chat's or a persona's picture
settings choose turbo, unless [image] turbo_model names a file of your own. A persona set
to Turbo on a server without the file is refused with a message naming that
command, and the setting stays until you change it. Switching between the
two models unloads the one not in use, and the first picture after a switch
pays the load.
Using it
Ask in plain words. The model describes the picture as a scene, and the
tool, not the model, writes the image model's prompt from it:
setting— everything but the people and the words: the place and its objects, or the whole subject of a picture without people;light,camera,style(a library style's name, only when you ask for a look),together(what the people do with each other) andtext(words to render exactly);people, each withwho,where(left, centre, right or background),wearing,doingandexpression.
It also picks a size: square (1024×1024), landscape (1344×768) or
portrait (768×1344).
- Text in images works well. Say the exact words; they go in
scene.textand are rendered as written. - Put people into a room of your own. Attach a photo of a place and ask for someone in it: the photo becomes the setting, and the people are drawn into it.
- Revise by talking. "Same thing, but at dusk" — the model sends only what changes, and the tool carries the rest of the scene forward from its record (below). Restating what is already true changes nothing, and a call that changes nothing draws the scene again at a new seed, which is what "try again" gets you.
- The model is not shown the result. It knows what it asked for, not
what came out, and is told never to say what a picture shows. A model that
can see images and has
image_viewlooks only when the task needs it — you asked it to check, compare or describe. Otherwise you are the judge; tell it what to change. - It works in any chat, read-only ones included. It only ever adds new
files under
images/in the conversation's own folder, so it needs no approval and no mode switch. - A picture takes about half a minute to a minute at the default 40 steps on the DGX Spark while the server has the model loaded; the first after the server has restarted to give its memory back takes two to three minutes. Anything else using the GPU at the same time — reading a reply aloud, say — slows it down.
- A new picture is counted before you see it. Image models sometimes
draw a person twice. After a new picture is drawn, mecha counts the
people in it, and when there are more than the scene has it draws the
picture again at another seed, up to twice more, and keeps the best. A
redraw adds a render's time; the count itself takes a second or two. A
picture that continues an earlier one keeps that one's seed so its room
stays the same, so it is counted but not drawn again: the result says
how many people it seems to show.
[image] people_check = falseturns the count off.
mecha run, mecha batch and evals can also pass a seed to reproduce a
new picture. A chat's schema has no seed, since models mostly copied an
earlier result's; every new picture there draws at a fresh one.
Pictures in web chat
In web chat a picture is drawn in the background: the reply can finish while it draws, and the picture lands on the call's card when it is done. Under each picture:
- Edit opens the edit panel (below).
- Regenerate draws the same picture again at a new seed, with no words and no painted area. The new one shows on the same card, with ‹ › to step between versions, and Edit, Regenerate and Download act on the version showing. It is off while a reply is running. On a persona call, Regenerate is in the picture viewer; talking over the redraw does not stop it.
- Download saves the picture to your device. It is there in every chat, incognito and a locked persona's included; the file is fetched and saved by the page, so no picture address lands in your browser's history.
- Save to library makes the picture a recurring character (below).
One picture draws at a time, and up to three more wait their turn. A picture asked for while another is drawing joins the line instead of failing; one asked for past that is refused, and the model is told so. While two or more are out the chat shows the line — the one drawing with its clock, then the ones waiting — and each waiting picture can be stopped on its own or dragged (or moved with ↑/↓) to a new place; the one drawing never moves. Stop on a picture stops that one, on the image server too; the call screen's Stop stops them all.
Editing a picture
The same tool edits. Hand it a picture and say what to change:
- One you generated: tap Edit under it. The edit panel shows the picture with a brush, a box and an eraser. Paint over (or box) the part to change and say what changes there ("make the dress green"): only the bright area is redrawn, and the dimmed part comes back exactly as it was. Paint nothing and the words edit the whole picture, unless they name one thing in it ("make the sky orange"): then the model can name that thing, the image server finds it, and only it is redrawn. The result says what was found, and says so when nothing was. In a persona chat you can paint up to four regions, each in its own colour with its own words. A face dropped on a region goes in along the face's own edges rather than your brush stroke, so the hairline and ears stay the photo's; say "face and hair" to take the hair too.
- One of your own: attach it with the paperclip, then say what to change.
Say only what changes. There is no need to ask for the rest to stay as it is: the tool writes that part of the image model's prompt itself, naming what the change leaves alone, because a prompt that re-describes the picture it already has measured worst at changing anything. What the model sends decides how the picture changes:
- A new pose, the camera, the setting, the light, or someone taken out redraws everyone on the scene's setting, so the camera actually moves and faces do not drift down a chain of edits.
- New clothes, an expression, someone added, or the words edit the picture.
- One small change to the picture itself — an object, a colour, a
detail — is a
retouch, with itsmasknaming where: the painted area, or a few words for the one thing to change ("the green jacket"), never a person's name or a position. Finding a thing by its words needs SAM 3.1, which installs with the image feature. A mask applies only to a retouch: when a call asks for a scene change and a mask together, mecha draws the scene change, ignores the mask, and reports that it did.
If an edit was meant to move things and the new picture's composition barely differs from the old one, the model is told plainly; a retouch of a colour or a detail is expected to keep the composition.
A painted edit is checked against the picture it changed. If a painted area comes back as it was, the result says the change does not show there rather than that the area was redrawn, and with several regions it names the ones that did not take. Words that ask for something to be taken out ("remove the cup") hide that area from the image model first, so it has nothing there to draw again.
In a persona chat, mecha draws the panel's edit itself and the persona only answers. A quick one-shot pass reads your words and what the picture was drawn as into a typed change; a painted area skips that reading and is drawn as you wrote it. A name the library does not hold, or a change that cannot be read, is said on the card and nothing is drawn, rather than a stranger. A change read as none draws the same scene again at a new seed. Then the persona replies in a line or two.
The edit is saved as a new file; the original is never touched. The result keeps the picture's shape unless you ask for a size.
Your photo is handed to the image server on this machine only, into a temporary folder it clears when it restarts. A large photo — anything over 4 megapixels, which is every phone photo — is scaled down and turned upright first, since the model works at about 1 megapixel anyway; its metadata, location included, stays behind. Your original file is not changed.
Recurring characters: the image library
Describe a person in words and the image model draws someone who fits the words — a different someone every time. To draw the same people across many pictures, keep them in the image library: a portrait and a short description per character, plus any styles you reuse.
Adding a character. In the web app's Library tab, tap Add
character, choose a front-facing portrait, and give it a name (maya) and a
short description that includes build and height. The picture is resized
before it is sent, and the photo's metadata, location included, is left
behind. Or, for a picture already in a chat, tap Save to library under
it. Add style on the Styles pane takes a name and a few lines on how the
pictures should look, and Edit on any character or style changes its
description or portrait. Pictures already made keep the version they used.
From a terminal:
mecha imagelib add-character maya --portrait maya.png \
  --description "a woman in her mid-30s with short curly black hair; slim, average height"
mecha imagelib add-style watercolour --text "loose watercolour, soft washes, paper texture"
mecha imagelib add-location boathouse --text "a timber boathouse, oars on the walls, a slipway door"
mecha imagelib add-reference boathouse --as view boathouse.jpg
mecha imagelib add-outfit red-raincoat --text "a red hooded raincoat, knee length, wooden toggles"
mecha imagelib add-reference red-raincoat --as view raincoat.png
A location is a place: its text, and up to three pictures, added on its
page in the Library tab's Locations pane or with --as view. A video clip whose scene names it (setting.location) is set
there, its first picture sent as the setting. An outfit is clothes: its
text, and a picture of the garment alone (on its page in the Outfits pane, or
--as view; no one wearing it). A
clip that dresses someone in it, by giving its name as their whole
wearing, sends the picture as what they have on, which keeps the exact
garment from shot to shot. Pictures don't use locations or outfit pictures
yet.
A small portrait can be redrawn larger. mecha imagelib upscale maya
asks the image model for the same photograph at about 1024×1024 and saves it
as a new version, the old one kept in its history; a portrait already that
size is left alone. With ArcFace installed (mecha imagelib face compare
fetches it), the redraw is kept only if it is the same face, and --out redraw.png writes it to a file to look at first. It matters most for video:
a clip is given each reference at most at its own size, so a small portrait
becomes a small, blurry face.
Using them. Name them in a chat, and say what each is wearing and doing:
"Maya and John sharing a picnic by a lake, in the watercolour style — Maya in
a straw hat pouring lemonade, John in a linen shirt, laughing." The model
lists each in scene.people by name; the library supplies their portraits
and descriptions, so their faces stay theirs. Up to five library characters
fit one picture, and a scene holds at most ten people.
- Someone is drawn only when listed as a person. A new picture that lists nobody but names library characters in its other words draws them. Otherwise a library name elsewhere in the words, for someone not in the picture, is read as "the viewer" rather than drawn as a stranger, and the result says so.
- "Me" is you when the library says which character you are. Run
mecha imagelib set-owner <name>once, and "me", "my" and "we" in what you ask of a picture name that character (and "we", you and the persona). Without it, you are the viewer: never drawn. - An edit carries the faces of the people it changes. Each library character an edit places or changes comes in as a head crop of their portrait beside their description, so a chain of edits does not drift into somebody else.
- A name still waiting for your approval is refused, never drawn as a stranger by that name.
- People who aren't in the library go in
scene.peopledescribed in words ("a waiter pouring coffee"), and are drawn as new faces each time. - A style the library doesn't have is left out, and the picture still
draws. The result names the styles the library has; a style written as
words ("Digital painting") finds the library's
digital-painting. The tool's description lists your styles so the model can name them; locked styles and character names are never listed. A look with no library name goes in words in the setting.
The model can propose characters. Ask it to invent one — "create a
recurring character called Sam, make his portrait, and add him to my
library" — and it stages him as a candidate. Nothing uses a candidate until
you approve it: in the Library tab under Waiting, or with
mecha imagelib list --all and mecha imagelib approve sam. You approve
exactly the text you were shown.
Reference pictures. A character can carry up to three kinds of extra
picture beside its portrait: a full body (head to toe, standing
square-on — its stance carries into pictures, and a new picture of that
character alone sends it; with anyone else in the picture, portraits are
sent instead, since two pictures each drew people twice), a face (for the
video tool), and up to four details such as a tattoo, each with a label
saying what and where. Add or remove them on the character's page in the
Library tab, or with mecha imagelib add-reference. You can also ask in
a chat — "save this tattoo picture to Wren as a detail" — and how that lands
depends on what the chat has read:
- a chat that has read nothing from outside (no web pages, mail or other third-party content) attaches it at once, shown as from a chat on the character's page, where you can remove it;
- a chat that has read outside content stages it in Waiting, with the
picture, for you to approve (or
mecha imagelib pendingandapprove-reference), because a reference rides into every later picture of that character; - an incognito chat always stages it, locked.
[tools] disabled = ["image_library_reference"] turns the chat door off;
your own page and the CLI are unaffected.
Locking. Locking a character hides the whole entry — card, portrait and
description — while you browse the Library tab; it still works in any chat,
and pictures already in your chats are untouched. The lock button at the top
of the Library tab shows locked entries until you lock again, reload, leave
the tab, or leave the page untouched for the autolock — 15 minutes unless
you change it under Settings → Lock (or mecha imagelib set-autolock <minutes>). The Personas tab shares the same lock and the same autolock.
With no password it is a plain toggle; to require one, set it once with
mecha imagelib set-lock-password. A character saved from a
picture made with a locked character starts locked; untick the box to save
it unlocked. One saved from an incognito chat is always locked. Locking
hides a character from then on; a portrait your browser already showed may
stay in its cache until you clear the site's data.
What a picture leaves behind
- A
.jsonfile beside each picture records how it was made: the seed, the size, the model and sampling settings, and which library entries (and which versions of them) it used. It holds no prompt and no scene words. - A scene record per chat. Each picture drawn in the assistant's web chat, a persona chat or an incognito chat records where it is, who is in it, and what they wear and do, so the next change starts from what the picture shows. The records are kept outside the model's workspace; an incognito chat's stays in its room. A picture brought into another chat is recognised by its content and keeps its scene. Deleting an assistant chat, or forgetting a persona chat's memories, removes the records it wrote.
- Each picture's prompt, for you, for now. Beside every kept chat's
transcript,
<chat>.prompts.logholds one line per picture: what was drawn, how, and the prompt the image model was given, so prompts can be studied and improved. Nothing reads it but you, an incognito chat keeps none, and forgetting a chat removes it.
What it will refuse, and why
- A server that is not on this machine.
urlmust be127.0.0.1,::1orlocalhost. Your prompts can contain anything the conversation holds, including private mail, and the tool declares that nothing leaves the machine — so it refuses to start otherwise rather than make that untrue. Because nothing leaves, image generation keeps working in a conversation that has read your mail, where tools that send are refused. - Starting without memory to spare. On machines where the GPU shares
system memory, a generation competes with everything else running, and
running out takes more than the image down. Before each picture the tool
asks the image server whether it already holds the model. If it does, a
picture needs 12 GB at the default, since most of the cost is already paid; if
it doesn't, it needs
min_available_mb(20 GB). A Mac's image server cannot say whether it holds the model, so a Mac always asks the full figure, 34 GB for its bf16 model. On top of that it keeps the memory floor's reserve free (8 GB by default) and declines while the machine is already stalling on memory. When it declines it says why, and which kinds of work hold the most memory; try again once a large build or another model has finished. After fifteen idle minutes it asks the server to unload its models. A servermecha features enable imageinstalled has a timer,mecha-comfyui-idle, that also restarts it after fifteen idle minutes; a hand-built one gets the same timer,mecha-comfyui-idle-reset, fromscripts/comfyui/install.sh. The restart returns nearly all of its memory, and a picture asked for during a restart waits for it instead of failing. An open ComfyUI page in a browser keeps a connection to the server and counts as use, so close it to let the memory go. - Leaving copies on the image server. The server's record of each job
(the prompt, the file names) is deleted when the job ends, however it ends.
Set
server_temp_dirand the uploaded pictures and the server's preview are deleted too; without it they stay in the server's temp folder until it restarts, and an incognito chat will not generate images at all. - A workflow or a prompt from the model. The workflow the server runs is fixed in mecha's code, and the image model's prompt is compiled from the scene by the tool. The model fills in typed values; it never writes the workflow, because an image server will run whatever workflow it is handed.